


Ask most marketing teams how they research their audience, and you'll hear the same three answers: personas, keyword volume, and whatever demographic data came bundled with the last platform they bought. That's not wrong, exactly. It's just incomplete.
We've written before about how audience understanding is the thing that gets you through the AI wave, and every wave after that. The point of that article was that empathy for your audience is the one competitive advantage that doesn't erode every time a search platform changes the rules. This one picks up where that left off. If audience understanding is the advantage, where does it actually come from? Here's the honest answer: it comes from a handful of sources most teams either don't know about or don't use consistently, and from a process for turning what those sources surface into decisions instead of decoration.
We'll start with the least surprising one. SparkToro has been a reliable part of our research stack for a while now, and it earns that spot honestly: it's one of the fastest ways to see where an audience already spends its attention — what they read, watch, follow, and listen to — without guessing. It's a good starting point for anyone doing this work. And we do mean starting point — it tells you where an audience is, but it doesn't tell you why they're there, and it won't tell you what to say once you show up.
This is where research used to get expensive. Understanding what an audience actually talks about — not what they say in a survey, but what they say to each other — meant manually diving into subreddits, reading threads, and pulling out patterns by hand. It worked, but it didn't scale, and it ate hours we'd rather spend acting on the insight than mining for it.
AI changed all that. Now we can point a tool — sometimes something we've built ourselves, sometimes an assistant like Claude — at the relevant corners of Reddit and get it to crawl, cluster, and summarize at a scale a person never could. What used to take a day of manual reading now takes an afternoon.
We'd be doing you a disservice if we didn't add the caveat: Reddit is a messy, unpredictable place, and AI summarization has a real hallucination risk. We don't treat what comes back as gospel. We treat it as a strong signal worth validating — which, as you'll see below, is exactly the position we take with every alternative data source on this list.
This one didn't exist as a category a couple of years ago, and now it might be the most important addition to the stack. As more of your audience's information diet runs through AI tools instead of a search results page, how those models describe, summarize, and position your brand matters as much as how a person would. We use a dedicated tool to track exactly that — what AI systems are saying about a brand's reputation, tone, and standing — because that perception is quietly becoming part of the audience's first impression before they ever land on a website.
We'll be honest: whether this counts as "audience research" is a fair question, and it depends on the angle you take. It's not audience data in the direct sense — it's not telling you what your audience wants. But it is telling you where everyone else is already standing, which is exactly the information you need to identify potential gaps where you can carve out a niche. We use competitive tools to see the landscape a given audience is already being pitched by, so that positioning and messaging can be built to be distinct rather than redundant. It's audience-adjacent, and it earns its place in the process because of what it protects against.
Here's the one that doesn't get called "research" often enough, even though it's the most honest data source on this entire list. Every piece of content and every ad we run generates real behavioral evidence: what people actually clicked, read, scrolled past, converted on, or ignored. That's not a proxy for audience understanding. That is audience understanding, collected at the moment it matters most.
We treat performance data as a continuous research loop rather than a report card. The metrics from what we published and ran last month directly shape what we test next, on both the organic and advertising side. It's the same discipline in both places: lay out a deliberate testing strategy, learn from what the data says, act on it, and repeat. It's the least glamorous data source on this list and the one we lean on hardest.
Collecting all of this only matters if it changes what we do next, so here's where it actually shows up.
The biggest shift these sources make is where we start. Instead of opening a project with a blank page and a guess, we open it already knowing where an audience spends attention, what they're actually saying in their own words, how they're being perceived, and what has already worked in market. That means the first bets we make aren't really guesses anymore — they're informed decisions, and they're usually good ones.
It also makes your testing more impactful. When you skip the upfront research, what you might call “testing” is often just throwing several ideas at the wall and hoping one sticks. When you start from real audience signal, testing becomes validation and continuous improvement. You're not asking "did anything work?" You're confirming that the smart bet you already had reason to believe in actually performed the way the data suggested it would, and refining through your follow-up tests. That's a faster, cheaper, and considerably less stressful way to run a testing program.
On the ad side specifically, this research is what tells us which platforms to prioritize first and which messaging angles are worth leading with, before a dollar of media spend goes out the door. That's the difference between testing your way to an audience and starting with one.
And it's woven directly into how we approach GEO. Every part of that process — the topics we choose, the way we structure content, the actual prompts and structures we build around — starts with audience motivators and pain points before anything else. That's the same audience-first thinking behind our take on navigating AI search — the tools change, but starting with the actual human on the other end of the query doesn't.
None of these sources is a silver bullet on its own, and that's sort of the point. SparkToro tells you where they are. Reddit tells you how they talk. Sentiment tools tell you how they're perceived. Competitive intelligence tells you what to avoid repeating. And performance data tells you, with total honesty, whether any of it actually worked. Put together, they don't just describe an audience — they make every bet after that one a smarter one.
This might sound like a lot when reading it, but for us it’s a process we have down — and it’s remarkably efficient. It’s the process we run for clients every day: pulling the alternative signal, validating it instead of guessing, and building content, ad, and GEO strategy on top of it from day one. If you'd rather have a team already running this playbook than build the muscle in-house from scratch, let's talk about what that could look like for your brand.
If you've been anywhere near the AI search side of LinkedIn in the last week, you've seen the chart. You know the one. The steep line, the two red dashed drops, the panicked captions. Klaas Foppen at Promptwatch flagged it first, Meenank Minnu asked what it means for Reddit-focused agencies, and LinkedIn ran it as a Top News story: "It looks like ChatGPT is breaking up with Reddit."
I spent an unreasonable amount of time this weekend geeking out about this one, so consider this the long version of the answer I've now given a few clients who messaged us asking, essentially, "should we panic?"
The tl:dr? No.
Depending on whose dashboard you trust, Reddit went from being one of the most-cited domains in ChatGPT Search to nearly invisible, in a matter of days.
The most-cited figures come from Promptwatch, an AI visibility platform. Their data shows Reddit holding a steady ~3.83% average share of ChatGPT Search citations from July 18 through August 7. On August 14, that collapsed to under 1%, settling at a 0.52% average through August 17. An 86% relative drop. There were two distinct moves: a smaller slide starting August 8 (when Promptwatch says ChatGPT changed its background query behavior), then the sharper cliff six days later.
Google's AI surfaces saw nothing like it during the same time frame. AI Overviews dipped about 11%, AI Mode about 30%, both gradual. Nothing resembling the cliff that was ChatGPT. That asymmetry is worth sitting with: whatever happened looks specific to how ChatGPT is searching, not some industry-wide reassessment of Reddit as a source.
OpenAI hasn't explained it. Gizmodo asked directly and got no response. Reddit, for its part, has pointed to other datasets that still rank it highly and told Axios the shift has "no meaningful impact" on its business, since LLM referrals are a small slice of its traffic anyway. As Melissa Rosenthal put it on LinkedIn, Reddit is arguably the best-positioned company to weather this (a signed licensing deal, a legal department, a public market cap) and it still found out its visibility had collapsed from a third-party dashboard, after the fact, the same way the rest of us did.
Losing citations is not the same thing as losing relevance. This what actually matters for strategy, and it's easy to miss if you're only watching some citation-share dashboard.
Suganthan Mohanadasan spent a few days last week reverse-engineering ChatGPT's new search tool calls directly from browser traffic. He found that when ChatGPT researches a commercial question, it fires a set of brand-specific searches with a roughly 30-day freshness window on each. And then, separately, it fires a Reddit-specific search with a freshness window of a year or two (usually because in one case, it was ten years). The Reddit query was asking what people are saying about the shortlist the model had already built from its own memory.
So in other words: the answer candidates chosen by Chat come from somewhere else, and Reddit gets pulled in afterward to gauge public opinion on them. In the one conversation he was able to check citation-by-citation, dozens of Reddit threads entered the model's context and zero got credited in the final answer.
That lines up with something Ahrefs has also found independently: across a large sample of prompts, ChatGPT pulls Reddit content constantly but cites it under 2% of the time. It's reading Reddit to build a sense of consensus and then attributing the resulting opinion to nobody in particular.
So the working theory, and the one that I agree with is that Reddit hasn't been dropped. It's become an invisible input. It's the behind the scenes people expert, shaping the tone and the verdict of an answer without showing up in the citation list. Which means citation-share data was never actually measuring Reddit's influence on what ChatGPT says. It was measuring what the response chose to display credit for.
Buyers are discovering, evaluating, and comparing brands through AI. 97th Floor CEO, Paxton Gray, is joining WordPress VIP CMO, Jodi Cerretani, for a three-part series on what that means for enterprise brands.
The same window that saw Reddit's citations fall also saw a shift away from a specific type of content: listicles and comparison pages or the "10 best," "X vs. Y" format that a lot of AEO/GEO playbooks were built around.
Data Tomek Rudzki at Peec AI shared with Lily Ray shows listicle citations dropping about 50% and comparison-page citations dropping about 32% in the period around ChatGPT 5.6's release, alongside a drop in the "best," "top," and "vs." style fan-out queries that made those page types easy wins in the first place.
When you look at these data points along with Suganthan's findings, it seems like there's a pattern there… ChatGPT appears to be deliberately combating the exact content types and sources that popular AEO/GEO tactics have leaned on hardest: pages built to win a citation rather than to actually serve a purpose.
Which is a very different story than "Reddit doesn't matter anymore."
One more thing worth flagging before anyone panics and rebuilds a strategy around a single stat, right now no one really agrees on the baseline. Promptwatch had Reddit's pre-drop share at 3.83%. Ahrefs, measuring the same period, had it at 16.7%. Gizmodo cited 4.5%. This reflects the differences we’re all struggling with when it comes to measuring impact on AI search. There are different prompt sets, different databases, different definitions of what counts as a "citation" in the first place. It's kinda like our own AI search version of Whose Line Is It Anyway, because everything's made up and the points don't matter.
Or more seriously, citation share should be used as a directional signal, not a KPI you hang your entire strategy on. And it's definitely not something to make a single-source decision on, whether that source is Reddit, Wikipedia, or Trustpilot.
No.
My take is this looks less like "Reddit is out" and more like OpenAI taking a deliberate swing at the AEO/GEO tactics that have flooded Reddit and listicle-style content with brand-planted mentions. If anything, that argues for a more intentional Reddit strategy, not abandoning one. Sure, the days of getting credit for volume are probably over, but genuine participation in communities where your audience already spends time was never really about the citation count to begin with.
Our head of search put it well: Reddit is still a massive platform with enormous organic traffic, and if your audience is there, that's reason enough to have a real presence, independent of what any single AI platform decides to cite this month.
The practical version of all of this:
We'll keep watching this, both because it's genuinely incredibly fascinating and because our clients' budgets depend on us getting it right. If you want to talk through what this means for your specific AI visibility strategy, that's a conversation we're always happy to have.
One of my favorite Chrome extensions is the Ahrefs SEO Toolbar. Click it on any page and you get a quick read on how that page is doing in search — domain rating, backlinks, keywords, traffic, the works. It's been a staple for a long time.
But here's where it starts to fall short: we're now optimizing pages for the prompts people are actually typing into AI tools, and a lot of those prompts simply aren't in Ahrefs' keyword database yet. That's especially true for pages we've just published or just re-optimized. So the tool that used to be the fastest gut-check on "how's this page doing" gets a lot less reliable right when we need it most — on our newest, most AI-focused work.
So Claude and I built something to fill that gap.
GSC Metrics Sidebar is a Chrome extension that shows you real Google Search Console data for whatever page you're on, right in your browser — no tabs to Search Console, no exporting, no digging through property lists. If it's a domain you have GSC access to, you get the numbers instantly.
View it in the Chrome Web Store →
Open the sidebar on any page and it pulls up:
Because this is pulled straight from Search Console, it doesn't matter whether the page went live yesterday or five years ago, or whether the queries it's ranking for are obscure, brand-new, or prompt-style phrasing Ahrefs hasn't indexed yet. If Google has data on it, you'll see it.
That's it. No extra setup, no config.
Watch my full walkthrough of the install and a live demo of the sidebar in action!
Grab it, install it, and start clicking around on client pages you're already working on. If anything looks off or you think of a feature that would make this more useful, send it my way — happy to keep improving it.
One more thing: this is exactly the kind of gap tools like Ahrefs can't close on their own right now — real performance data on the AI-driven queries our AI Search Services are built around. If you're needing a clearer read on how your content is actually showing up in AI search, reach out.
Over the past few weeks we've made a case in pieces. A ten-minute exercise with no keywords surfaced a 40% gap in mature, keyword-researched content calendars. G2's buyer data showed that half of B2B software buyers now start their research in an AI chatbot — asking questions that generate no trackable search data at all. And before any of that, we argued that keyword research could no longer be step one of a content strategy.
Fair response: okay — then what is step one?
The answer is the same one it’s always been for us: the audience. What’s new is the discipline behind getting there — in July, we rebuilt the process our teams use to turn that belief into a repeatable strategy.
We’ve said “audience first” since before GEO was an industry term. What’s changing isn’t the belief — it’s the machinery underneath it, and the case for changing that machinery stacked up fast this year. Because of that, we built our new process around one irrefutable mission statement: it's our job to figure out what questions people are asking, and to make our clients become part of the answer.
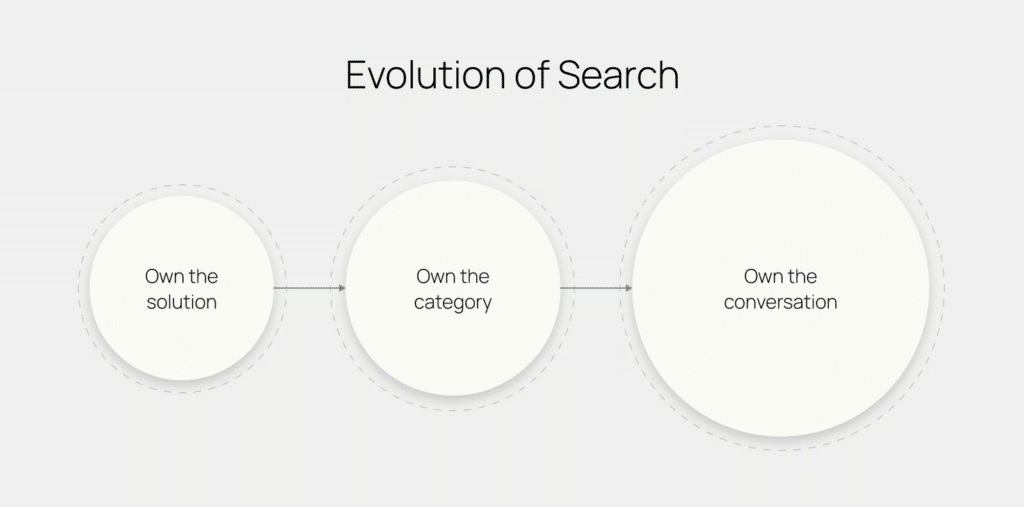
Search has gone through three eras of what winning meant. Early on, brands had to own the solution — people searched for the thing they already knew they wanted, and you fought to show up for it. Then search got bigger, people researched more, and it became our job to own the category — this is where classic keyword research was born: low-hanging fruit, content gaps, topical authority, hub and spoke. Now the search universe has exploded again, across AI assistants and conversational queries, and the job is to own the conversation — every question a buyer asks on the way to a decision, most of which no keyword tool can see.
Here's the friction, and we'll be honest about it because every experienced SEO feels it: a lot of this demand can still be captured by traditional keyword research. So why change anything? Because we tried the obvious shortcut — starting with keywords and expanding them into prompts — and it doesn't work. The prompts that come out of keywords are limited to the pool the keywords define, and when you push AI tools to generate them, you get generic, low-quality "what is X" questions. Starting from the audience produces a far larger universe of real questions; the keyword data then attaches to it, rather than defining it.
And to be equally clear about what we're not doing: we're not abandoning traditional SEO. Every client still has 5–10 non-negotiable core keywords tied directly to their product and revenue, each classified by the strategy it needs — Watch (already won, defend it), Win (can realistically capture #1), or Invest (long-term authority play). One of our e-commerce clients has held the #1 position for their money keyword for over five years, and we still track it, still build to it, still defend it. That work doesn't stop; it's just no longer the whole strategy.
Before the steps, the allocation decision that makes this a different process rather than the old one with new vocabulary: content volume is weighted roughly 45% problem-aware, 45% solution-aware, and 10% decision-stage.
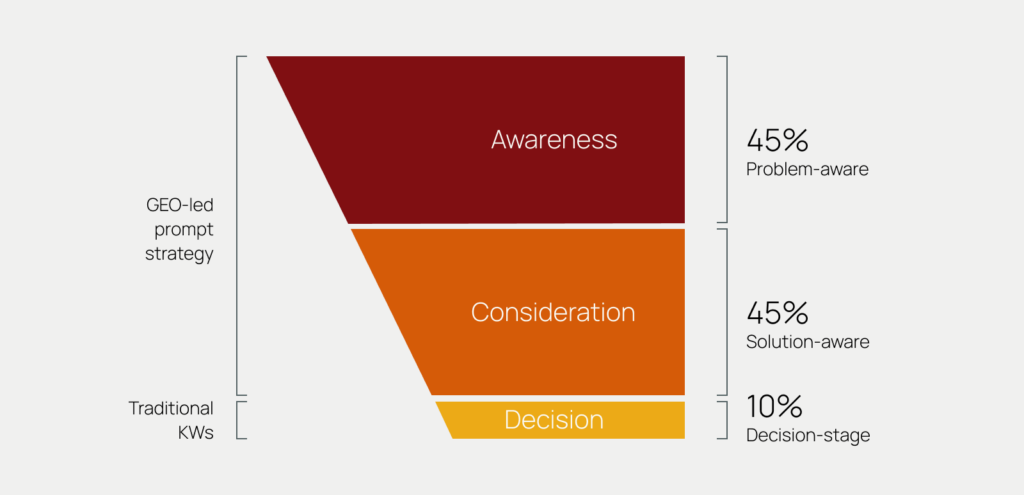
That looks inverted if you grew up on keyword-first strategy, because it puts 90% of the work where the trackable volume can’t be found. But the early and middle journey is where AI-era research thrives — the long, contextual questions that change buying decisions. It's also where most opportunity is undefended, because everyone in your category is working from the same keyword dataset and converging on the same expensive bottom-of-funnel terms. The decision stage still matters and still converts, but you need to support your core keywords.
The strategy is built by two roles working as a duet — a content marketer who owns the audience, and a search marketer who owns the data — creating a collaborative harmony that achieves our audience-first, data-backed output.
We start with personas built on audience research and client priorities — primary motivators and pain points guided by focus products/services and UVPs. We also look at how long their buying journey runs. That last detail shapes everything downstream: a quick-purchase product leans harder on traditional keywords and conversion content, while a long B2B sale needs a much bigger upper funnel.
At the same time, we classify the client’s 5–10 core keywords as Watch, Win, or Invest, and confirm with the client that we’re building on the right foundation before going further.
Now the exercise we ran company-wide becomes a formal step. For each persona, at each stage of their journey, instead of leaning on traditional keyword research, we write the real questions they’d ask — fears, objections, comparisons, buying concerns — sourced from customer interviews, sales conversations, and how the brand already shows up in AI search. Awareness-stage questions stay diagnostic (“why is my interest rate higher than expected”), not solution-focused (“which lender should I choose”), because that’s how real buyers actually think before they’re ready to decide.
Here's where keyword data re-enters — as evidence, not as the gate. Each question gets paired with the keyword that best represents it — chosen for how well it captures the question, not just its metrics — and scored on search volume, traffic potential, difficulty, and CPC.
Notice what the score does and doesn't decide. A prompt with weak keyword signals doesn't automatically die — it's flagged as a risk signal, and it might still be worth building for AI visibility. Search volume is evidence of demand, not the boundary of demand.
This is the most crucial stage: raw research becomes a prioritized strategy, and it happens through scoring rather than vibes.
Every topic gets three scores, one from each side of the duet, plus one that only exists because both sides agreed to be scored:
• Audience score: how many personas care, and how much the topic could sway a buying decision
• Client score: how directly it ties to the client’s revenue and stated priorities
• Demand score: search volume, traffic potential, keyword difficulty, and CPC, combined into one number
The three combine into a single ranked list. So when a team is staring at 150 possible topics wondering where to start, the answer is already sorted — by audience, business, and data together, with no single input allowed to take the lead. That’s the point. Plenty of teams claim to be audience-first right up until the sort-by-volume click. The scoring makes the claim structural.
Before building anything new, we check it against what the client already has. If an existing page is close to the mark, we optimize it instead of creating a duplicate — a small step that makes the most of existing resources (and as a bonus, saves a client from ever hearing “we recommend a new page” about something already sitting on their site).
From there, related topics get consolidated, and distinct audiences get split apart — for example, prompts would diverge for anxious parents and undergrads around the topic of student loan cosigning. These would be two content pieces, not one, because they're two audiences with two different intents.
Building the content calendar from there is easy — the strategic thinking already happened upstream.
Tracking starts the moment the calendar goes live, and it runs on layers rather than a single line. Traditional keywords and custom prompts are tracked side by side. Search Console gets watched for the long-tail, question-shaped impressions that new content should start earning. And around those, the downstream signals of AI visibility: brand mentions, citations, referral traffic from AI platforms, branded search, direct traffic, and — critically — conversion rates on high-traffic pages, because the endgame of zero-click research is a visitor who arrives already convinced and converts at a higher rate. Any one of those lines is easy to argue with. Layered together, the trend is hard to deny — which is exactly what reporting in a zero-click era has to be able to survive.
A process this concrete invites a misunderstanding: that GEO is only this. It isn't. Around the strategy build sit the factors that don't fit in a scoring column but move AI visibility anyway: technical optimization, original research and proprietary data (which win disproportionately in AI answers), unique points of view, content atomization and distribution, freshness — sometimes the right calendar entry is re-optimizing something you shipped eight months ago — and brand reputation, without which none of the rest gets very far. Those get their own treatment in how we brief GEO content versus SEO content and in why E-E-A-T matters more in AI search, not less.
None of this is keyword research's obituary. It's a reassignment. Keyword data is still genuinely excellent at four jobs: validating demand the persona work surfaced, forecasting the trackable portion of the opportunity, client education (numbers persuade stakeholders in ways personas don't), and the decision-stage plays it was always built for — including those 5–10 core keywords every client will always have.
What it lost is the job it was never qualified for: deciding what your audience cares about. Start with the human, weight the work toward where they actually are, and bring the data back in where it tells the truth. Trust us, it works — this approach grew one client's AI search results 261%.
That's the process now guiding how we build strategy for every client engagement. The next question is what it surfaces for yours.
Want to hear this philosophy debated out loud? This episode of The Campaign goes deep on audience-first marketing:
Want to see what this process would surface for your brand? Start with a free AI audit, or explore our GEO & AI Search services.
There's a version of the AI search conversation that treats all of this as a future problem. Someday buyers will research in ChatGPT. Someday AI answers will shape deals. Someday you'll need a strategy for it.
G2's research on B2B software buying says the someday already happened.
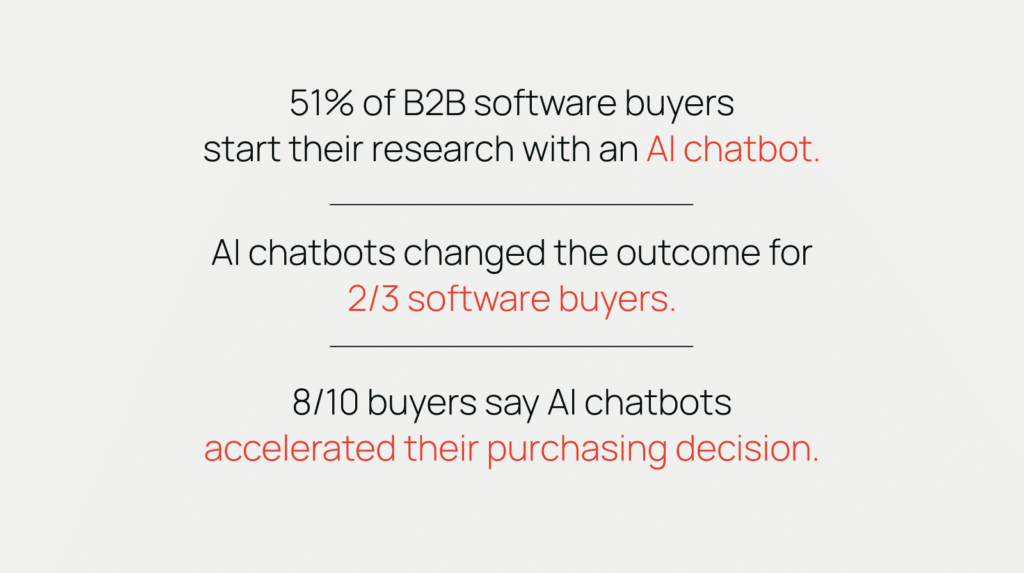
Per G2's report, The Answer Economy: How AI Search is Rewiring B2B Software Buying, 51% of B2B software buyers now start their research with an AI chatbot. Not "have tried one." Not "consult one at some point." Start there. The first touchpoint of the modern software deal — the moment a buyer goes from feeling a problem to naming it — is now, for the majority of buyers, a conversation with an AI.
We put this data in front of our entire company at our monthly meeting, because it reframes everything about how we think content earns pipeline. Here's why it stopped us in our tracks — and what we think it demands of every B2B marketing team.
The adoption number gets the headlines, but it's actually the least interesting of G2's findings. Buyers moving to a new research channel is a distribution story — marketers have navigated those before. The next two stats are a different kind of story.
AI chatbots changed the outcome for two-thirds of software buyers.
Read that again. Not "informed their thinking." Changed the outcome. Two out of three buyers who used AI in their research ended up somewhere different than where they were headed — a different vendor, a different category of solution, a different shortlist entirely.
This is the part that should reorganize your marketing priorities. A traditional search engine handed your buyer ten links and let them assemble their own conclusion. An AI assistant hands them the conclusion — a synthesized recommendation, a comparison table, a "for a team your size, I'd look at these three." The AI isn't a new place buyers gather information. It's a new participant in the decision. It has opinions, and buyers are taking them.
Buyers are discovering, evaluating, and comparing brands through AI. 97th Floor CEO, Paxton Gray, is joining WordPress VIP CMO, Jodi Cerretani, for a three-part series on what that means for enterprise brands.
And 8 out of 10 buyers say AI chatbots accelerated their purchasing decision.
Faster deals sound like good news, and for the vendors in the answer, they are. But think about what acceleration means mechanically: the research phase compresses. The weeks a buyer used to spend reading blog posts, downloading comparison guides, and sitting in your retargeting audience — the entire window where marketing traditionally worked on them — shrinks to a handful of AI conversations. Buyers are arriving at shortlists before most vendors' funnels even register that a deal exists.
Put the three numbers together and the picture is stark: the majority of buyers start in an AI, most of them are redirected by what it says, and nearly all of them move faster because of it. The buyer's journey didn't add a new step. It got a new gatekeeper.
Here's the mechanism underneath the "changed the outcome" stat, and it's worth understanding because it's genuinely different from how search shaped decisions.
In traditional search, the buyer did the synthesis. They'd search "best project management software," open six tabs, weigh the review sites against the vendor pages, and form a consideration set themselves. Your job was to be present at enough of those touchpoints that you made the list. Imperfect, but the buyer was the editor.
In AI-era research, the model is the editor. When a buyer asks, "We're a 40-person agency with clients in healthcare — what project management tools handle HIPAA compliance well?", the AI composes an answer from everything it knows and everything it retrieves — and the vendors named in that answer are the consideration set. There's no page two. There are no ten blue links to scroll past the answer. For a growing share of buyers, if you're not in the response, you were never in the deal.
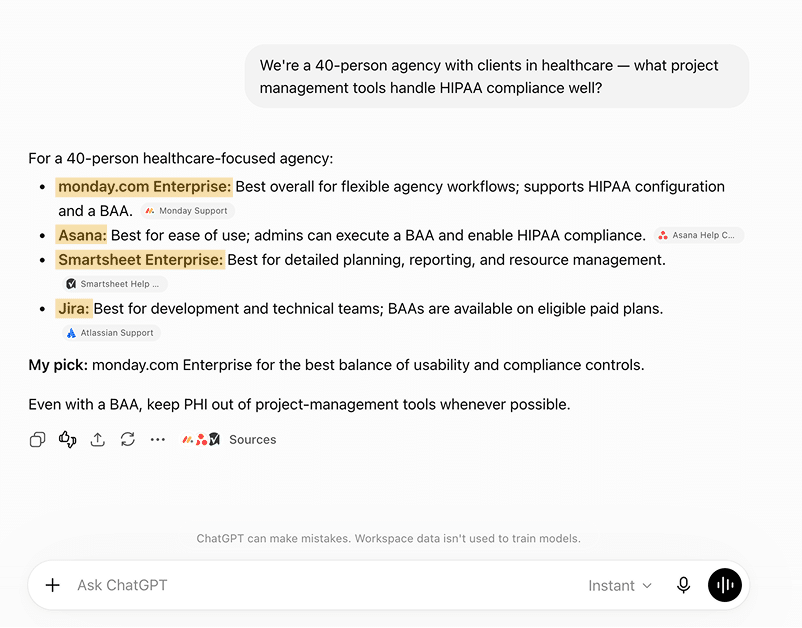
That's why buying outcomes are changing. The AI doesn't just reorder the same shortlist buyers would have built anyway — it builds a different one, weighted toward whichever brands are most legible to it: clearly explained, widely referenced, credibly reviewed, easy to cite. Brands that dominated the old game of rankings can be invisible in this one, and challengers with clearer, more citable material are showing up in answers next to incumbents ten times their size.
If your analytics look fine, that's not evidence this isn't happening to you. It's the nature of the shift.
Those AI research sessions happen off your properties, generate no impressions you can count, and mostly resolve without a click. The buyer who asked an AI four questions about your category, got steered toward a competitor, and never visited your site doesn't show up anywhere in your reporting. Neither does the one who was steered toward you — they arrive later as "direct" traffic, unusually educated, unusually far down the funnel, and your attribution model shrugs.
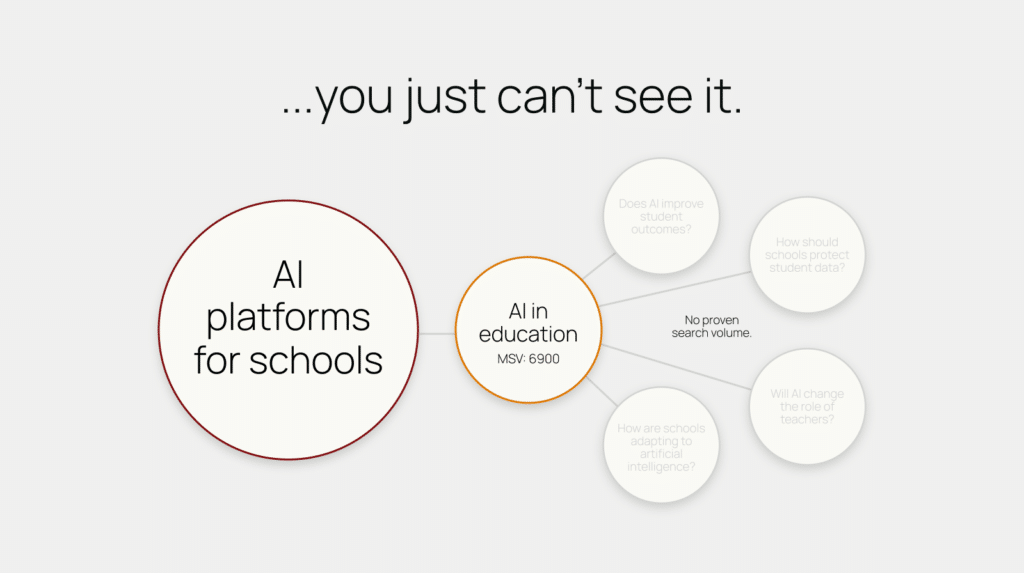
This is the same visibility problem we've written about across this series: the most important buyer activity in your category no longer produces trackable data. When we ran a keyword-free content exercise across our whole company, roughly 40% of the ideas our teams generated — the real questions real buyers ask — weren't covered anywhere on existing content calendars, because nothing in the keyword data ever pointed to them. The G2 numbers are the demand-side confirmation of the same story: the buyer conversation moved somewhere your dashboards can't follow.
Just because you can't see it doesn't mean it isn't happening.
The question every CMO should be asking isn't "should we respond to this?" The buyer already moved; that decision was made for you. The question is whether your brand is in the answers — and there's a concrete way to work on that.
Start by auditing your presence where buyers actually start. Ask the major AI assistants the questions your buyers ask — not your keywords, their questions. "What should a company like X consider when solving Y?" "Compare the top options for Z." Note who gets named, who gets recommended, what's said about you, and what sources the answers cite. This is the new SERP audit, and most teams have never run it. (If you want a head start, we run a free AI audit that measures exactly this.)
Then build for the questions, not the keywords. The prompts steering these deals — "I have $50,000 and a mandate; where's the highest-impact place to put it?" — have no trackable search volume and never will. They come from understanding your buyer: their fears, frustrations, objections, comparisons, and buying concerns at each stage of the journey. That's why we've stopped treating keyword research as step one and started from the audience instead, with keyword data brought back in later for validation and forecasting. Search volume is evidence of demand, not the boundary of demand.
Make your material easy to cite. AI assistants recommend what they can confidently parse and attribute: clear claims, specific comparisons, transparent pricing and capability information, third-party validation, structure a machine can lift an answer from. This is where E-E-A-T implementation for AI search stops being an abstract quality guideline and becomes a revenue lever. Vague thought leadership doesn't get cited. Direct answers to real questions do.
And measure the new funnel honestly. Sessions and rankings won't tell you whether you're winning in AI answers. Citation share, brand mentions across AI platforms, and the volume and behavior of branded and direct traffic will. This work compounds: one of our clients grew AI search results 261% with a topic cluster strategy built for exactly this environment. The teams that build this richer view of organic now are the ones who'll be able to show the work paying off — and keep investing in it — while everyone else argues with their attribution model.
Every stat in the G2 report will keep climbing. The 51% becomes 60%, then 70%; the buyers who haven't moved yet are the trailing edge, not the resistant core. Which means right now is the strange, brief period where the buyer behavior has already shifted but most vendors' strategies haven't.
That's not a threat. For any brand willing to move, it's the most asymmetric opportunity in B2B marketing: your competitors are still optimizing for a journey buyers are abandoning, while the new gatekeeper is still deciding whom to trust.
Half of your buyers are starting their next purchase in a chatbot. The only question left is what it says when they ask about you.
Want to know how your brand shows up in AI answers today? Get a free AI audit, or explore our GEO & AI Search services.
Platform properties are now available to everyone. Google announced this month that the feature has rolled out globally in Search Console, along with a new performance guide for social and video content. If you missed the original announcement, we covered it in full when the feature first launched — read that article here for a breakdown of what platform properties are and how to set them up. This article is about what to do next: how to actually use this data to your advantage.
First, a quick refresher on why this data is different. The data you get from Google Analytics is valuable primarily because it's your data. You own the domain, the tracking code fires on every user interaction, and you get to see how customers move through your content, which channels drive traffic, and where the journey breaks down. But your website is only one of many places your customers find your brand through search. Your YouTube channel appears in search results. So does your Pinterest profile, your TikTok account, even your Instagram posts. The difference: you don't own those platforms, so you've never had visibility into how people find your brand there.
Google Search Console has always been the exception, it shows data owned by Google, not dependent on a tag firing on your site, showing you exactly how your domain gets found organically. Platform properties extend that same visibility to the profiles you maintain on platforms you don't own. That's a genuinely new window into your brand's search footprint. Here's how we recommend using it to build effective content strategies.
Buyers are discovering, evaluating, and comparing brands through AI. 97th Floor CEO, Paxton Gray, is joining WordPress VIP CMO, Jodi Cerretani, for a three-part series on what that means for enterprise brands.
When you connect a platform property and open the Performance report, you're looking at the actual search queries that led people to your Instagram posts, TikTok videos, X threads, or YouTube content. These are a direct read on what your audience is typing into Google when they're in the market for the kind of content you create. And because this data lives outside your website, it often captures demand that never shows up in your standard GSC property or GA4 at all.
Start by filtering the Performance report by query rather than by post. Look for terms generating consistent impressions across pieces of content across multiple platforms— that's your clearest signal of which topics Google associates with your brand. This is actionable whether Google has it right or wrong. If the association is right, you've confirmed your positioning. If it's wrong, you've found a disconnect between the content you're producing and the brand you're trying to build.
Pay close attention to the gap between impressions and clicks. A post sitting at thousands of impressions with a low click-through rate usually means one of two things: either the content isn't compelling in how it appears in search results, or the query intent is better served by something other than a social post. Say one of your TikToks is pulling 12,000 impressions on a "how to" query but converting under 1% of them to clicks, don’t mistake that for a failing video, that's a searcher who wants a step-by-step guide, not a 30-second clip. Cross-reference these queries against your domain's GSC property, and you have a prioritized list of content your site is missing for topics Google already associates with your brand.
The introduction of AI Overviews (AIO), along with Google making every SEO's life harder by making positions 1–100 nearly impossible to track, has injected a lot of unknowns into content planning. Keyword research is less accurate than it used to be, and the keyword datasets from SEO tools are no longer as reliable or actionable. Content strategy has started to feel like guesswork.
Platform property data gives you a faster, more grounded way to pressure-test topics before you commit significant resources to them. Here's the logic: if your social or video content on a topic is already generating impressions and clicks through Google Search, that isn't projected demand from a keyword tool. That's actual people looking for that content right now. It's the kind of validation that moves a topic from "we think this might work" to "we have evidence this works" in one report.
The practice is simple. Before greenlighting a major content investment such as a pillar page, a video series, a guide, first filter your platform property queries by the topic and look at the impression trend over the last 28 days. Growing impressions across multiple posts? Green light. Flat or nonexistent? Either the demand isn't there or Google doesn't yet see you as relevant to it, both of which are worth knowing before you spend the budget. This works in reverse, too: topics your team is convinced are winners but that show zero organic pickup across any platform deserve a hard look before the next quarter's calendar gets built.
Topic clusters have been a staple of SEO strategy for years: a pillar page supported by related content, interlinked to signal depth on a subject. Platform properties let you extend your topic clusters beyond your domain.
Think about how Google now sees your brand. It isn't just crawling your website, it's also crawling and indexing your YouTube explainers, your Instagram carousels, your TikTok tutorials, and your X threads, and platform properties show you which of those are earning search visibility. When your blog post, your video, and your social content all rank for queries within the same topic neighborhood, you're demonstrating authority on that subject across the entire search results page, not just in the ten blue links.
Use your platform property data to find the clusters that are already forming. Pull the top queries from each connected platform and group them by theme. Where you see the same topic surfacing across two or more platforms plus your domain, you have an emerging cluster, ready to be reinforced. Fill the format gaps: if the topic has a strong video and a strong blog post but nothing on social, that's your next carousel. Where a topic performs on social platforms but has no corresponding pillar on your site, that's your next long-form piece, and your existing social content becomes the distribution engine for it the day it publishes.
It is also essential to convey the same messaging and be consistent on unique value propositions, products and offerings, and overall voice of your brand across all platforms. You are trying to build an entity on the web that clearly tells Google who your brand is, what you do, and who you serve. That messaging needs to be consistent across all platforms that talk about your brand.
The goal is to stop treating your website content and your social content as separate strategies with separate teams and separate calendars. Google is evaluating your brand's expertise holistically. Your planning should work the same way.
The teams that get the most out of platform properties won't be the ones who check the report once out of curiosity. They'll be the ones who build it into their operating rhythm.
Add a platform property review to your monthly or quarterly content planning sessions, right alongside your standard GSC and GA4 reporting. Three questions worth asking every time:
This is also a report worth putting in front of stakeholders who don't live in Search Console. Social teams have historically had to justify their work with platform-native metrics such as likes, follows, engagement rate. These never quite connect to the pipeline. Platform properties give them something new: proof that social content is capturing organic search demand, in the same report and the same language the SEO team already uses. For agencies and in-house teams alike, that's a bridge between two functions that have been measured separately for too long.
Platform properties won't replace your keyword research or your analytics stack, but they close a visibility gap that's existed as long as brands have had social profiles. The brands that win with this feature will be the ones who treat it as a strategy input, not a vanity report. Connect your platform properties this week, and if you want help turning what you find into a content strategy, we can support. Let’s talk.
If you can't track where your traffic comes from, how do you prove your marketing works? It's the question keeping marketers awake right now as zero-click search dismantles the link between a question and a website visit. But here's the thing: We’ve been here before.
In 2013, a report existed that no marketer could produce today. It showed a client's organic keywords next to their monthly search volume — standard stuff. But the column next to it was the one worth staring at: exact visits, by keyword, down to the misspellings. Not a rounded estimate. Not a range. A number like 19 visits from "employee rewards program," 6 more from its singular form, and a dollar figure attached to each one specific enough to say, out loud, to a client: this keyword drove $13,750.30 in revenue last month. That kind of precision was normal.
Then, later that year, Google rolled out a Secure Search update. Overnight, that column went dark — just row after row of “(not provided)” — which became the tongue-in-cheek name for the event. Every marketer running paid or organic search lost the ability to tie a keyword to a visit, to a dollar. They were also left explaining to their bosses why half of what they were used to seeing in a report could no longer be found.
It read like an extinction event. If you can't prove which keyword paid for itself, how do you justify the budget behind it? How do you do the job at all?
Here's the part that's easy to forget more than a decade later: The data didn't come back, and the industry didn't collapse. SEO and content marketing kept absorbing bigger budgets, kept getting more competitive, kept becoming a default line item instead of a nice-to-have. One company’s own trajectory makes the point bluntly — the same business doing roughly $120,000 a month in total revenue when "(not provided)" hit was doing something like 8x that by the summer of 2026. That's not a story about one agency's growth engine. It's a data point inside a much bigger one: an entire industry kept expanding after losing the single metric everyone assumed it couldn't survive without.
The reason is simpler than it feels in the moment. Nobody had the data. Not your agency, not the client's last agency, not the biggest competitor in the space. When an entire industry loses the same piece of information at the same time, the businesses that pull back and the businesses that keep going are separated by something other than access to better numbers — because there is no better number to access. They're separated by whether they kept showing up for an audience that, "(not provided)" or not, was still searching, still buying, still there.
It also helps to be honest about how solid that lost data actually was. Search volume was never a hard count — it was a bucket. A keyword estimated at "10" a month might really be 7 or 13; Google just rounds it into the same tier. At real scale, the buckets get enormous: A keyword estimated at 246,000 monthly searches might genuinely be anywhere from roughly 190,000 to 300,000, and it still gets reported as one tidy number. Even today, research from Ahrefs puts their own keyword-volume accuracy at around 60%, and Google's own Keyword Planner is even lower than that. Their CMO's response to the criticism was blunt: directionally accurate is accurate enough. The precision the industry mourned in 2013 was, in large part, always a little bit of a story marketers told themselves.
Buyers are discovering, evaluating, and comparing brands through AI. 97th Floor CEO, Paxton Gray, is joining WordPress VIP CMO, Jodi Cerretani, for a three-part series on what that means for enterprise brands.
Search is going through another one of these moments, and it has a name: zero-click search. AI Overviews, AI Mode, ChatGPT, and a growing list of assistants now answer the question directly, inside the search or chat interface, before a user ever lands on a website. The visit that used to generate a session, a pageview, a trackable event — the raw material attribution was built on — increasingly never happens at all. That's not a smaller version of the "(not provided)" problem. It's the same problem at a larger scale: the industry is once again losing the clean, attributable trail between a person's question and a business's website, only this time it's not one column in a report, it's the click itself.
And the audience isn't waiting for marketers to catch up. Google has said AI Mode now sees over a billion users a month, with query volume roughly doubling each quarter. ChatGPT is now among the five most-visited websites in the world. Research from G2 found that 51% of B2B software buyers now start their research inside an AI chat interface, that two-thirds say what the AI told them changed the direction of their decision, and that 80% say it made them buy faster than a traditional search journey would have. The audience is unmistakably there — it has simply moved to a place that's harder to measure.
The panic this produces is familiar, because it's the same panic. Brands are asking whether their traffic decline means their strategy failed, whether they picked the wrong platform, whether the whole channel is breaking down. Usually none of that is the actual problem. The problem is that the tidy, attributable version of the data that made everyone comfortable is gone, and comfort is not the same thing as evidence of demand.
Both moments — 2013 and now — reward the same instinct and punish the same mistake. The mistake is treating the loss of a metric as a signal to pull back, to wait for a new dashboard before doing anything differently. The instinct that wins is simpler and less comfortable: stop trying to measure the audience perfectly and start following it directly. In 2013, that meant investing in search and content even without a dollar figure attached to every keyword, because the audience was still searching whether or not anyone could prove it. Today it means showing up in AI Overviews, in chat answers, in zero-click results, because that's where the questions are being asked now — whether or not a session ever gets logged for it.
Search volume, keyword data, and attribution reports were always evidence of demand, never the boundary of it. Losing the cleanest version of that evidence hasn't shrunk this market once in its history. It has only ever separated the companies willing to adapt and go where their audience actually is from the ones waiting for the data to make that decision feel safe. The first group is the one that keeps growing.
Uncertainty is uncomfortable. But an industry that only invests when it's certain isn't managing risk — it's guaranteeing it'll be standing still when the data finally catches up to where the audience already went.
Have you ever been in a meeting where a client asks if [insert whatever trending GEO tactic of the week] will help them show up in AI search, and you have to take a deep breath before crushing their hopes?
We’ve all been there. The AI search landscape has everyone looking for a magic bullet, but the reality of what actually moves the needle is far more complex. And unfortunately there is such a massive disconnect right now between what we think drives AI search and what actually works that misinformation has taken root and spread faster than we can debunk it.
There is an organizational behavior theory from back in the day that I feel like can actually work really well in explaining why some strategies help you win at AI search and some don’t seem to make any difference, despite everyone claiming it will.
It’s called Two-Factor theory.
Buyers are discovering, evaluating, and comparing brands through AI. 97th Floor CEO, Paxton Gray, is joining WordPress VIP CMO, Jodi Cerretani, for a three-part series on what that means for enterprise brands.
If you’ve never heard of two-factor theory, here’s the tl:dr
It was introduced in 1959 by Frederick Herzberg and posits that employee workplace satisfaction and dissatisfaction are driven by two different sets of factors, hygiene factors (or dissatisfiers) and motivators (satisfiers).
Hygiene factors are factors that when absent or not enough or done poorly, employees become dissatisfied (hence the name). But fixing and/or providing only prevents dissatisfaction, it doesn’t actually inspire and motivate employees to do better work. These are typically outside of the work of a job itself, and are things like working conditions, coworker relationships, good supervisors, and believe it or not, salary.
Motivators on the other hand, are typically intrinsic to the actual work and job. They're the things that drive people to perform their best, to innovate and be creative, to go the extra mile, and truly feel committed to their jobs. They’re less tangible typically too - stuff like opportunities for growth, doing meaningful work, a sense of accomplishment, being recognized and valued, being trusted and given responsibility.
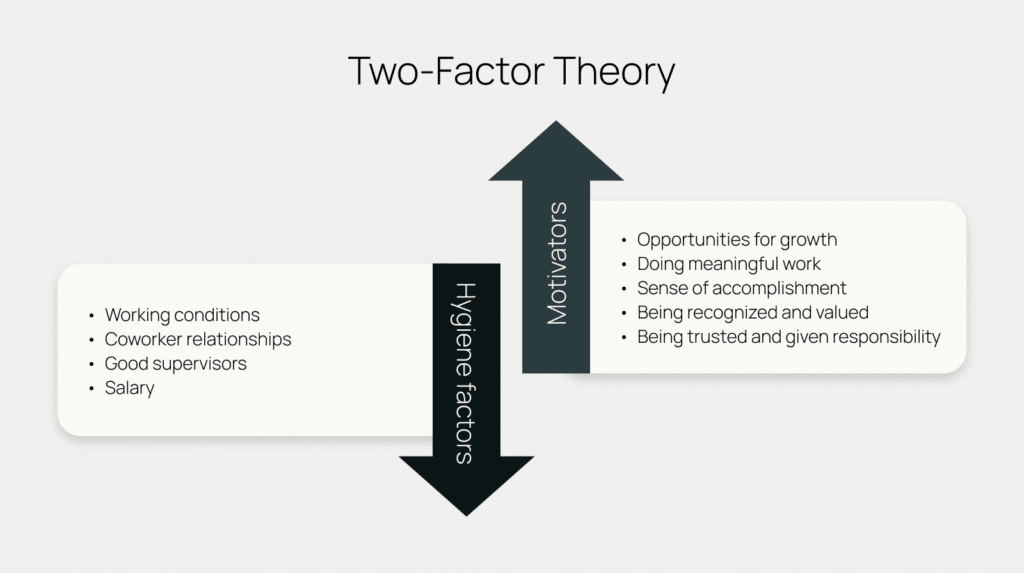
Herzberg theorized that both must be taken care of, eliminating dissatisfiers and focusing on creating satisfiers, in order to have motivated employees.
Whether you agree or disagree with the theory, it's a really interesting way of looking at things. The more I’ve thought about it, the more I’ve realized that it can be extended to contextualize things outside of human behavior.
In particular, I feel as if many AEO/GEO tactics become a lot clearer (and why you don't always get the results you want) when viewed through the lens of two-factor theory.
Now keep in mind that this is just an analogy. It's not a perfect one to one. Just like people who are more complex than two factors, so is search in today’s modern landscape.
So what are the hygiene factors for AI?
Think of them as the things that, if not present or done poorly, literally bottleneck an LLM's crawling behaviors and make it harder for AI to parse your site. Things like schema, llms.txt, ungated robots.txt, good heading structure, clear URL paths, optimized meta descriptions, and a solid technical site architecture. Basically, anything that establishes a clean semantic layer—the stuff that delivers your content clearly and cleanly so the machine can actually read it.
When people are searching for a magic bullet, often it feels like hygiene factors are the things that get recommended. Typically because they’re a lot easier to implement and feel more tangible. However, months later, after tests have been run, and we don’t see an uptick in traffic or mentions or citations, everyone throws their hands up and says well that clearly doesn't work, and moves on to the next shiny new magic bullet.
And well, yeah, of course it didn't work the way you wanted it to. It's a hygiene factor! You essentially just paid the entry fee to get parsed. It's only going to cause problems if it's not there (or done poorly), but it's not going to motivate the model to choose you.
The things that actually are going to get you cited, ranked, mentioned, whatever, are never going to be quick fixes. Just like with humans, they’re going to take a little more effort and time to cultivate.
An AI obviously doesn't feel brand loyalty; it relies on mathematical weights, entity recognition, and semantic relationships. So when we talk about motivators for AI, we're talking about authority, expertise, unique voice and insights, and brand recognition. Essentially, a holistic brand strategy.
It means actually having a product or service that's worth talking about and not just a copycat. If your content just regurgitates the exact same points as everyone else, an LLM has no mathematical incentive to cite you over the original sources. Unique insights create novel semantic connections, giving the model a reason to pull your specific perspective into a generated answer. These motivators are so much harder to replicate and cultivate. But truly, it's what's going to get you the win far more than any hack out there.
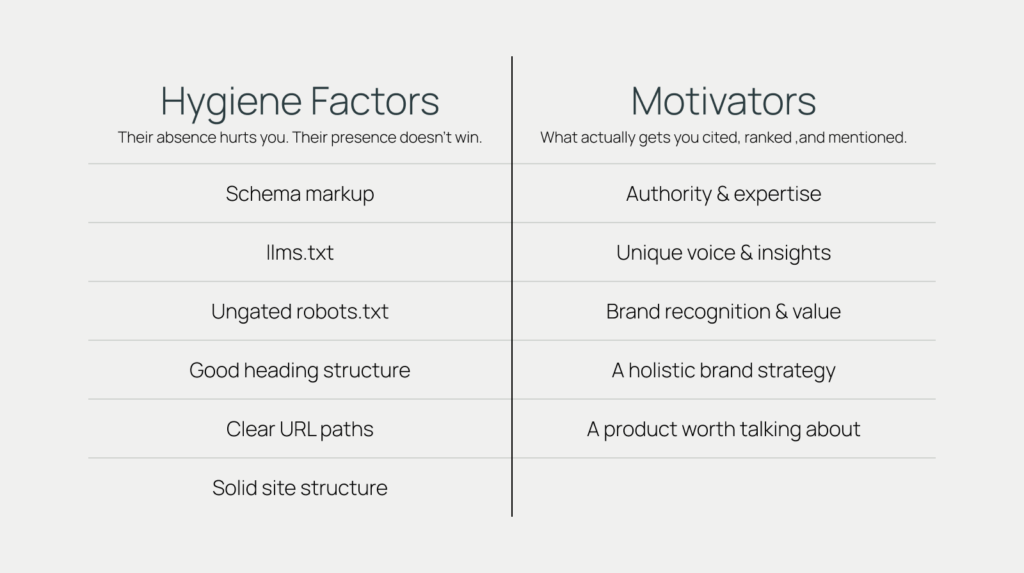
The next time you hear about a new GEO tactic , or a client asks if a specific tweak will guarantee them a spot in AI overviews, ask yourself: Is this just making it easier for the machine to read us, or is this giving the model a reason to actually care about us? Or essentially …is it just good hygiene or is it an actual strategy?
If it’s only the first, you’re just preventing dissatisfaction, not actually winning AI search.
